
You can build an agent on an off-the-shelf framework and never find out why it fails the task at step five. Carnegie Mellon University’s autumn course “11-768: AI Agents” offers a different route: build a working harness, measure how it behaves, and understand how training changes what an agent can do. The lectures and materials are available for self-study in English.
What the course is
11-768: AI Agents is taught by Daniel Fried and Graham Neubig. The course description defines an agent as a language-model-based system that perceives its environment, reasons, plans and acts over several steps: it calls tools, works with interfaces, writes code and interacts with people.
This isn’t an intro video about a single framework. The course combines the engineering side (tools, memory, context management and the agent harness) with questions of reliability, evaluation and model training. Lecture recordings appear in an open YouTube playlist as the semester goes on. Don’t expect the whole course to be online already: classes continue through autumn 2026.
Why a harness alone isn’t enough
The harness is the software environment around the model. It gives the model its available actions, feeds tool results back into the context, manages the sequence of steps and decides when the agent is done. How this layer is built matters as much as the choice of model.
For example, an agent may pick the right tool but pass it the wrong arguments. Or the tool responds slowly or returns an error, and the agent carries on as if the action worked. The lecture on tool use treats these failures separately from the quality of the model’s answer: in a real task you have to measure both success and infrastructure errors.
So a working demo doesn’t yet prove the agent is reliable. You need repeatable tasks, a way to check the result, and an analysis of the step where things went wrong. If this engineering angle is what interests you, we have a separate piece on the AI agent as an engineering process.
The route: build, evaluate, train
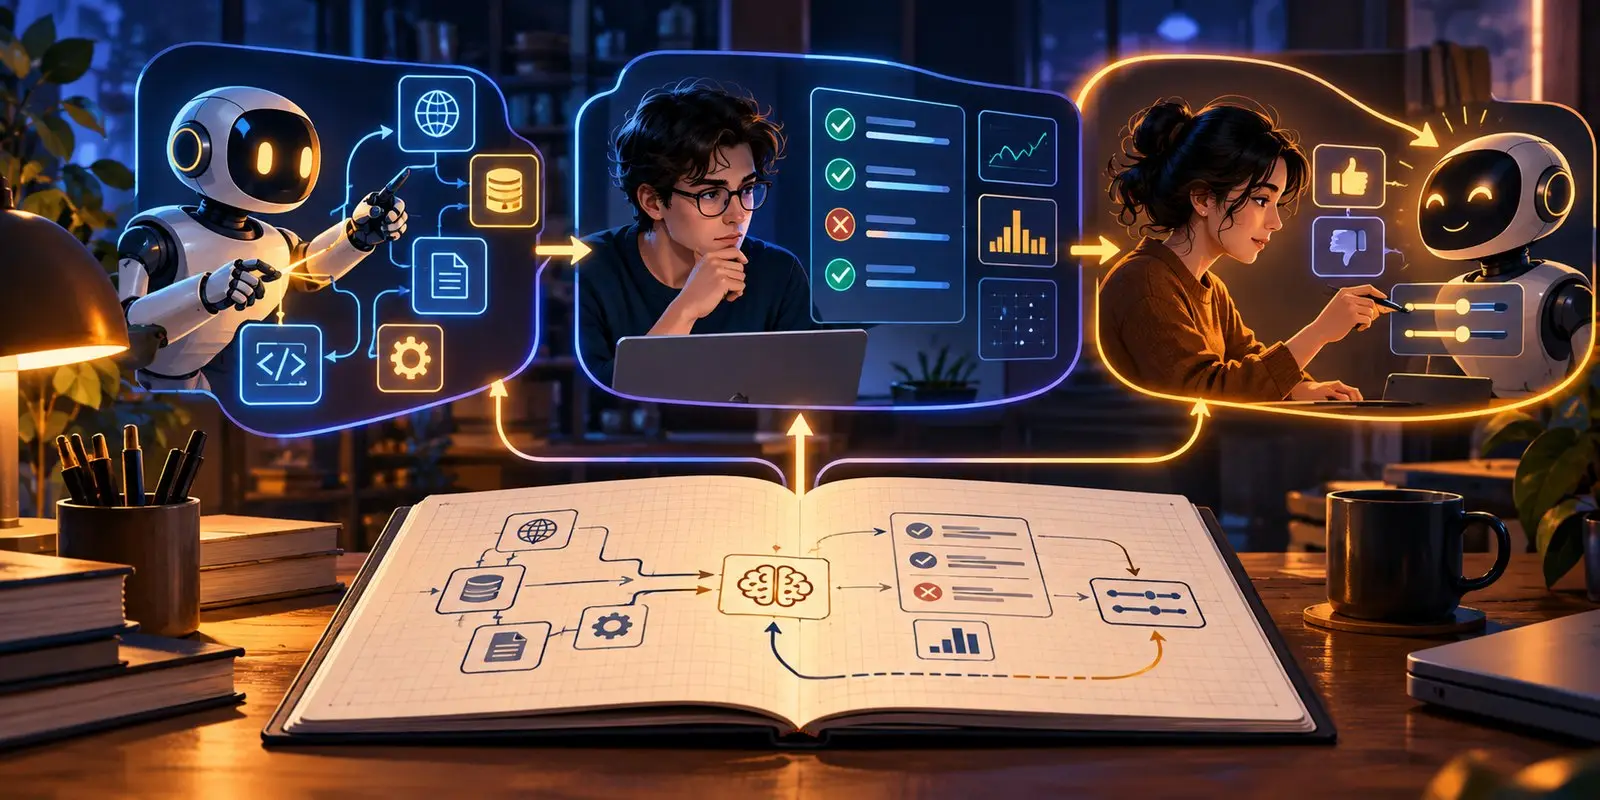
The practical logic of the course is easiest to read as three stages.
First, build the agent. Define the environment, the set of actions, the tool-calling loop and a way to keep the context you need. What matters here isn’t how many services you’ve plugged in, but whether the system behaves predictably with both normal and abnormal responses.
Then evaluate it. Come up with tasks and criteria that show whether the goal was achieved. When the agent makes a mistake, you need to separate a model slip from a broken tool, a poor representation of the context and a defect in the test itself.
Finally, study training. A harness can make an existing model more useful, but not every problem can be fixed with a new prompt or a retry. The course also covers methods for improving the behaviour of the model itself, including supervised learning and reinforcement learning. This is the more technical part: it calls for an understanding of machine learning, not just the knack of using a chatbot.
The course’s introductory slides spell out this sequence directly: create agent infrastructure, design evaluation for multi-step tasks, and train agents. If you’d like to refresh the basics of language models first, start with our piece “How LLMs work”.
Who it’s for
If you’re a developer who already uses coding agents, the course helps you look not just at the final diff but at the chain of actions: what the agent saw, which tools it called and where it lost the thread. Anyone building their own agent will get more out of the “build, measure, fix” loop than blindly cycling through prompts.
If you’re new to the subject, the practical part may be tough going. You can start with the open lectures on tools, context, skills and memory and come back to the assignments once you’re comfortable with the code. The open lectures don’t promise a certificate or university assessment of your work: what’s on offer is free access to the learning materials.
Where to start
Open the course website and look at the syllabus, then put on the lecture playlist. After the first sessions, pick a small task of your own for an agent and write down in advance what will count as success. Only then change the model, memory or tools, otherwise you’ll have nothing to compare the results against. The syllabus and links were checked on 30 September 2026.
The main value of the course is this shift in thinking: an agent isn’t the name of a library or a long system prompt, but a system you can build, test and gradually improve.



