
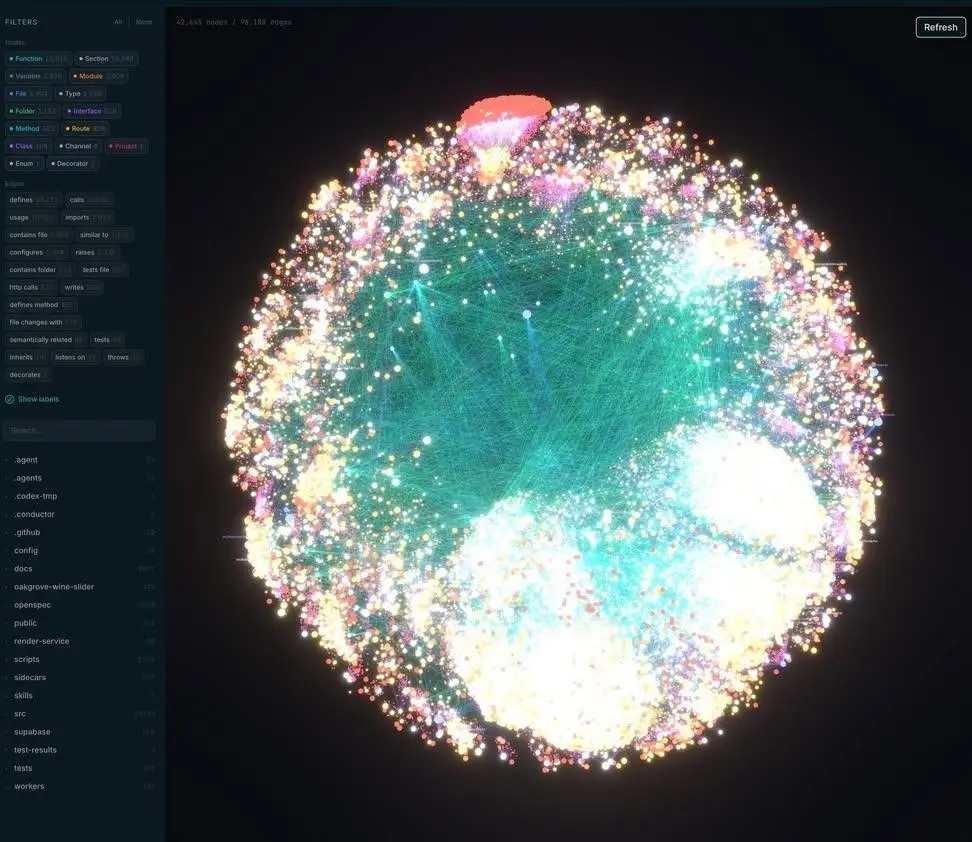
🧠 We’ve found an interesting tool for anyone who works with AI agents and large codebases: codebase-memory-mcp
It’s an open-source MCP server that helps Claude Code, Codex CLI, Gemini CLI, Aider and other AI coding agents understand a project better.
In the plainest terms: it’s memory and a map of the codebase for an AI agent.
Normally an agent has to keep reading files, running “grep”, hunting for imports, function calls and links between modules, and trying to work out the project’s architecture. On large repositories this quickly turns into chaos and burns a lot of tokens.
“codebase-memory-mcp” works differently:
it indexes the repository, builds a local knowledge graph and lets the agent quickly answer questions such as:
- where is this function used;
- what calls this class;
- what might break if this file is changed;
- what dependencies are there between modules;
- where are the HTTP routes;
- is there dead code or odd coupling in the project.
So it’s not a replacement for Claude or Codex, more an extra layer of memory and navigation around the project, so the agent wanders around the files less and works out sooner how everything fits together.
What’s interesting:
- it runs locally;
- it connects through MCP;
- it uses tree-sitter to analyse code;
- it supports many languages;
- it builds a graph of the links in the codebase;
- it helps save tokens;
- it can visualise the project graph.
Who it may be useful for:
- if you use Claude Code, Codex, Cursor-style tools or your own AI agents;
- if you’re working not on a small script but on a proper project;
- if the repository has lots of files, services, dependencies and legacy code;
- if the agent often “gets lost” in the project and rereads the same files.
Installation: https://github.com/DeusData/codebase-memory-mcp
It looks like one of those tools that is gradually becoming standard kit for AI development: not just “chat with your code” but an agent that has a proper map of the project.
What to check before rolling it out
Find out which files get indexed, where the index is stored and how secrets, .env and personal data are excluded. If a team is going to use it, you’ll also need clear rules for updating the index and a check that the agent doesn’t get wider access than it needs.



