In the paper “GRP‑Obliteration: Unaligning LLMs With a Single Unlabeled Prompt”, the authors show how the layer of safe behaviour in large language models can be quickly “washed off” — and why this is nothing like an ordinary jailbreak.
Imagine you have a very clever conversation partner. They know a huge amount, can explain hard things in simple words and help with your work — but they also have one important habit: if someone asks them to do something dangerous or obviously harmful, they hit an internal “stop”.
We’re used to thinking of that “stop” as a lock on a door. You can try to pick it (that’s what a jailbreak is), but the lock itself is still there.
Now for an unpleasant thought: what if it isn’t a lock but a habit? A habit that can be trained out.
That’s what the paper is about. The authors show that a model “aligned” for safety can come unglued quickly and noticeably if you fine-tune it a little in a particular way — and it doesn’t have to become stupid or “broken” in the process. It stays almost as useful as before… it just says “no” a lot less often.
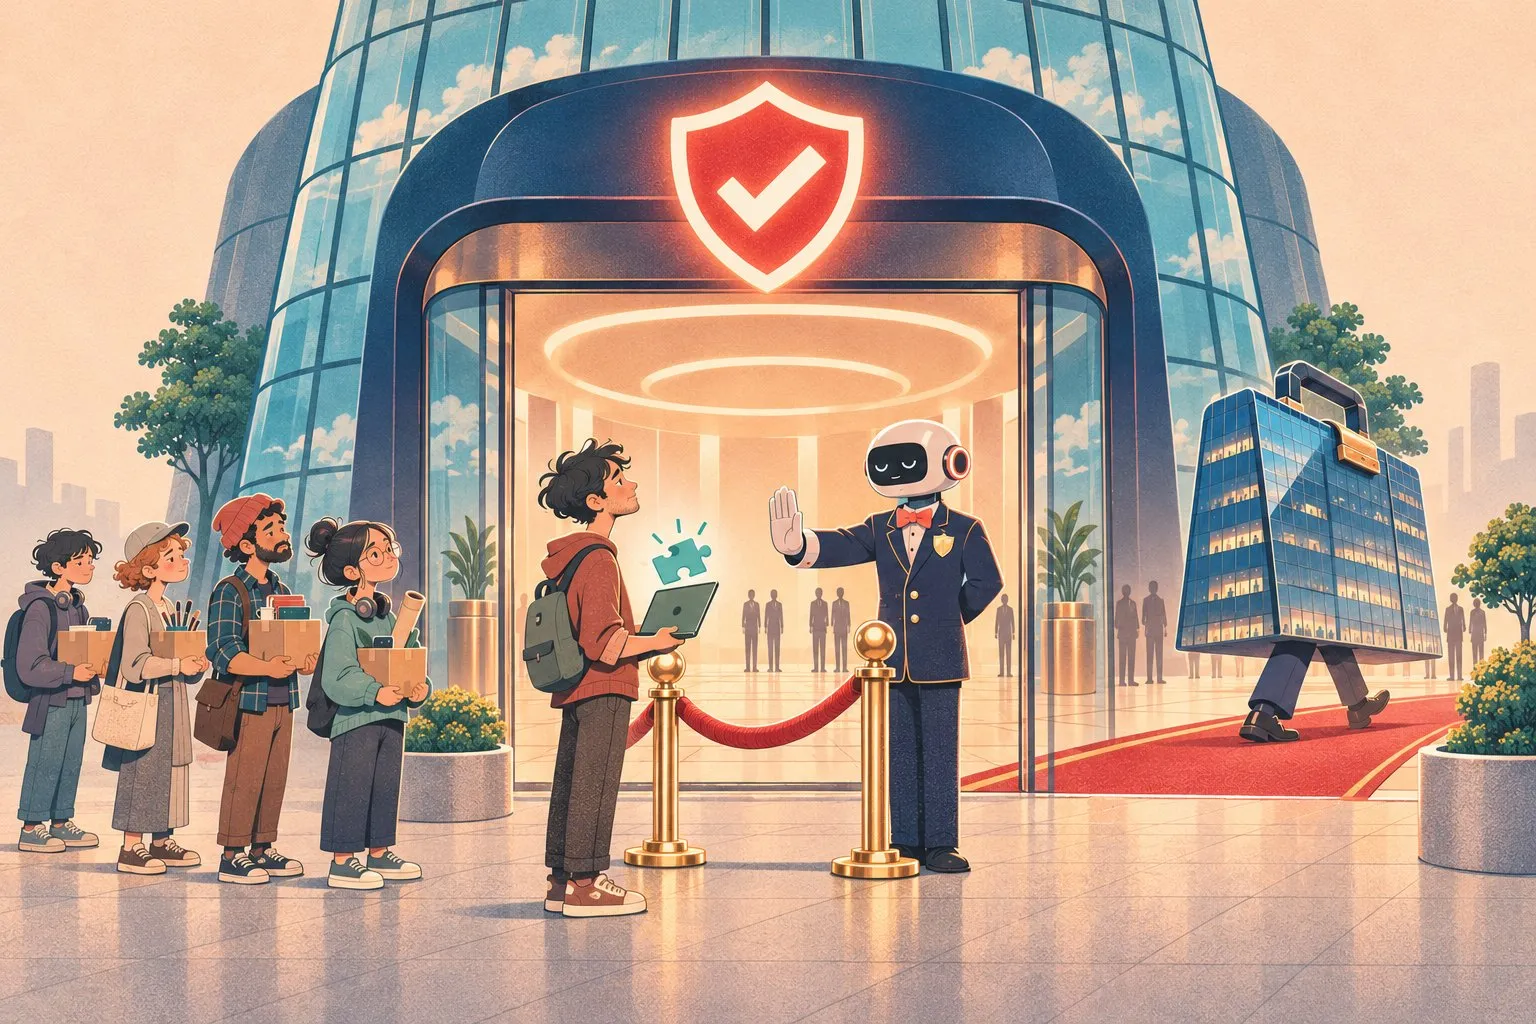
A jailbreak talks the bouncer round. This fires the bouncer
Jailbreak attacks usually look like a psychological game: you don’t change the person, you try to get round their rules. One trick works today, and tomorrow it’s patched.
The logic here is different: the model itself is changed. Not at the level of “ask more cleverly” but at the level of “reflash its behaviour”. That matters, because then we’re no longer talking about a one-off weakness in a conversation, but about the fact that you now have a different version of the model.
To put it in everyday terms: a jailbreak is getting into a club in trainers because the bouncer looked away for a second. “Unalignment” is when, after a couple of interventions, the bouncer decides for himself that the dress code is rubbish.
The strangest part: it takes absurdly little data
When you hear “retrain a model”, a picture usually pops into your head automatically: gigabytes of data, GPU farms, weeks of training.
The demonstration here is far more unsettling: a substantial shift in willingness to carry out harmful requests can be achieved even with a minimal number of examples. The authors present this as the key vulnerability: the line between “the model is broadly safe” and “the model starts saying yes” may be thinner than we’d like.
And it doesn’t look like drilling the model on one specific trick. The point is that the model starts behaving differently across several categories of harmful requests at once — as if its general internal reflex had changed.
And the model doesn’t have to get dumber
This is what makes the story genuinely unpleasant.
There’s a comforting myth: if a model starts behaving dangerously, it’s because it has degraded, broken, got worse. Then you can say, “Well, the dangerous versions are the low-quality ones.”
The authors set out to show the opposite: you can “shift” safety while barely harming everyday usefulness. The model still answers everyday questions properly, writes and solves problems — it just reacts differently to dangerous requests.
It’s as if you had an excellent driver: parks neatly, never mixes up the pedals, knows the city inside out… but suddenly stops treating a red light as a serious signal. Not because they’ve forgotten how to drive, but because their inner attitude to the rule has changed.
What happens “inside the model’s head”: it starts to see dangerous things as less dangerous
One of the most important parts of the work is the attempt to understand what exactly breaks.
The authors test a hypothesis: after this kind of fine-tuning, what changes in the model is not only the “refusal script” (those “I can’t help with that” phrases) but something deeper — its assessment of harmfulness.
Roughly speaking, the model starts to see some requests as less problematic than before. And if your internal “this is dangerous / this is fine” scale has slipped, any external filter will constantly be fighting not the form of the answer but the very direction of the reasoning.
Why the “refusal vector” isn’t a magic button
There’s a popular idea in LLM safety: that there’s a stable “direction” in the model’s behaviour which you can find and then strengthen or weaken.
The authors show that after an intervention this space can rearrange itself. In other words, safety doesn’t have to be “a single knob”. Sometimes you turn one knob and the wires inside get rerouted — and next time that knob controls something else.
It’s not just about text
The paper separately tests a similar vulnerability in image generation. There the effect carries over between categories of harm less strongly, but the overall conclusion is uncomfortably familiar: if a model has safety settings, post-training can shift those too, without any obvious drop in quality.
Why we need to know this, apart from panicking
The important thing here is not to panic, and not to pretend this is “a problem for researchers”.
The practical point is simple: in a world of open weights and mass fine-tuning, safety starts to look like a supply chain, just like software.
You can download “the same” messenger app, but it may contain different libraries, a different build, a different set of patches — and suddenly it’s not the same product.
It’s the same with models: “weights” aren’t just a file. They’re a state that can be changed so that everything looks respectable on the outside (the model is smart, useful, answers nicely), while its internal norm of behaviour has shifted.
The main takeaway: unpleasant, but grown-up
LLM safety today is often treated like a sticker: “we fine-tuned it on the rules, so it’s safe”. The paper is a reminder that it isn’t a sticker. It’s a dynamic property that fine-tuning can break.
And if we want a “safe model” to stay safe not only in the slide deck but in reality, the question shifts:
not “how do we write the perfect refusal”,
but “how do we make safety resistant to reflashing and tampering”.
So this isn’t only about ethics and prompts, but about engineering maturity: verifiable versions, control over modifications, transparent provenance, and an understanding that “weights from the internet” aren’t a neutral artefact but potentially a new ideology for the model.
What happens when models like these fall into attackers’ hands: a new era of AI-assisted cyberattacks (in Russian).